
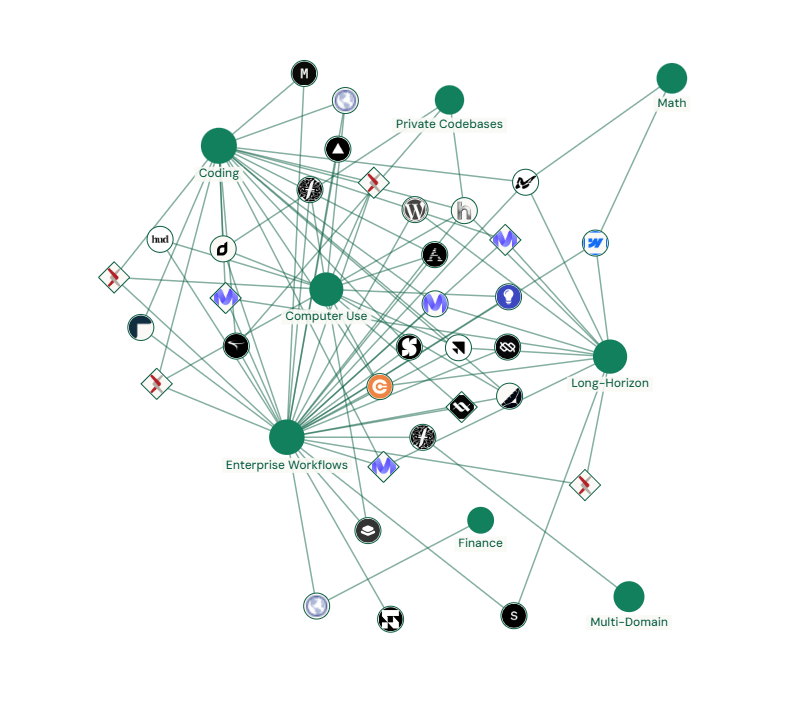
Software teams have a well understood vocabulary for technical debt, shortcuts taken now that cost more to fix later. AI research infrastructure accumulates a version of the same problem, but it is often harder to see coming. A custom training environment that seemed like a reasonable shortcut six months ago can quietly become the reason a team cannot reproduce its own earlier results, compare fairly against a competitor, or onboard a new researcher without weeks of undocumented context. Starting from a maintained RL environment directory instead of ad hoc, custom infrastructure sidesteps a lot of this particular flavor of debt before it accumulates.
Why This Kind of Debt Is Easy to Miss Early On
A custom environment usually works fine for the person who built it, which hides the debt entirely until someone else, a new hire, a collaborator, a future version of the same researcher months later, tries to use it without the original context.
By the time that mismatch becomes visible, the cost of fixing it has grown considerably, since months of results may now rest on an environment nobody can fully explain or reproduce cleanly.
The irony is that the very speed that made a custom shortcut appealing in the first place is exactly what gets lost later, once someone has to spend weeks reverse-engineering decisions the original author made from memory and never wrote down.
How to Avoid Accumulating This Debt
Document environment decisions as thoroughly as code, including why a particular environment or benchmark was chosen over alternatives, not just how the code itself works.
Favor environments with existing documentation, source availability, and known benchmark comparisons over custom builds whenever the underlying problem does not genuinely require something novel.
Treat documentation as part of the actual deliverable, not an optional extra to add later, since infrastructure without documentation quietly becomes a liability the moment anyone other than its author needs to touch it.
What Careful Teams Do to Prevent This
Teams that build on environments sourced from an established RL environment directory inherit documentation, known benchmarks, and a track record of use by other teams, which sidesteps a meaningful share of the debt that accumulates around fully custom, undocumented infrastructure built under early deadline pressure.
Several research leads specifically mentioned that onboarding new team members became noticeably faster once their infrastructure was built on well documented, widely used environments rather than internal tools only the original author fully understood.
One team lead described the difference plainly, saying a new hire went from confused to productive in days rather than weeks, simply because the environment they were working with had documentation and a public track record instead of a single person’s scattered memory.
Where This Awareness Is Headed
Expect more AI teams to treat environment and benchmark choices as a debt-management decision explicitly, weighing the short-term convenience of a custom build against the long-term cost of maintaining something only one person truly understands.
Conclusion
Technical debt in AI research hides differently than it does in typical software, often invisible until someone other than the original author needs to use the work. Building on infrastructure sourced from a well documented RL environment directory avoids a significant share of that hidden cost, leaving a team with research built on a foundation other people can actually understand, reproduce, and build on later, long after the original author has moved on to something else.